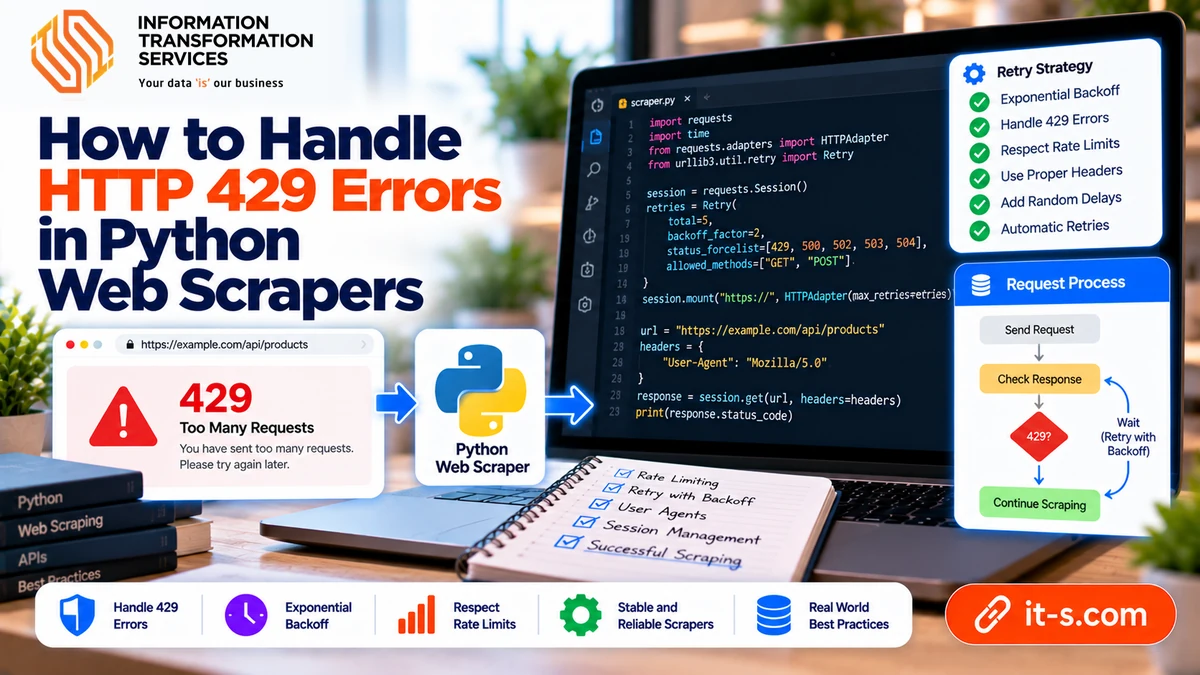
How to Handle HTTP 429 Errors in Python Web Scrapers
An HTTP 429 response can stop a Python web scraper even when its selectors, login details, and parsing logic are correct. The server is saying that the client has sent too many requests within a particular period. Repeating the same request immediately is rarely a useful fix. It can extend the restriction, waste resources, and make a scheduled extraction job less reliable.
A better scraper treats rate limits as operating constraints. It sends fewer unnecessary requests, reads the server’s retry guidance, reduces concurrency, and records enough progress to resume safely. This guide explains how to diagnose 429 responses and design a respectful recovery process without trying to evade a website’s access controls.
Understand what a 429 response actually means
The 429 Too Many Requests status is different from a normal parsing failure. It is an HTTP response, so the server or an intermediary received the request but declined to serve it at the current rate. Limits may apply to an IP address, API token, user account, route, or an entire service. Different endpoints can have different quotas.
A single 429 does not prove that your IP is permanently blocked. It also does not guarantee that waiting a few seconds will restore access. Check the response status, headers, request history, and the website’s published usage policy before deciding how to recover. The MDN explanation of HTTP 429 describes the status and its optional retry guidance.
Distinguish rate limiting from other failures
Log the actual status code instead of classifying every unsuccessful request as a block. A 401 can indicate missing authentication; a 403 may indicate denied access; a 404 usually means a resource was not found. A 500-series response points toward a server-side failure. These conditions should not all trigger the same retry loop.
Also inspect whether the problem occurs on every request or only after a burst. If the first request succeeds but the next twenty fail, pacing is a plausible cause. If the first request returns 403, increasing delays alone will not resolve an authorization problem. Diagnose the response before changing the scraper.
Read the Retry-After header before choosing a delay
Some 429 responses include a Retry-After header. It may specify a number of seconds or an HTTP date. Treat that value as the server’s instruction about when to try again, not as a suggestion to shorten the wait. If a response asks for a lengthy delay, pause or reschedule the job rather than tying up a worker indefinitely.
When the header is absent, the client needs a conservative fallback policy. The absence of a header does not mean immediate retries are acceptable. Set a maximum wait, record the rate-limit event, and avoid issuing another batch while the current request is still being throttled.
Set a request budget before starting a crawl
A request budget limits how many pages the job may fetch during a defined interval. If a documented API allows sixty requests per minute, target a lower sustained rate to leave room for occasional retries and other processes sharing the credential. An HTML website without a published quota deserves similarly cautious pacing based on its responses and access rules.
Think in terms of total requests rather than only successful pages. Redirects, repeated detail-page fetches, failed retries, and parallel workers all consume capacity. A crawl that appears to request one product per second can generate substantially more network traffic if each product triggers several supporting requests.
Use exponential backoff instead of a tight retry loop
Exponential backoff increases the wait after repeated transient failures. A simple sequence might pause for one second, then two, four, and eight seconds. This reduces pressure on a service that is already refusing requests. It is a fallback when the server has not supplied a more specific Retry-After instruction.
Backoff should have a ceiling and a finite attempt count. Waiting longer forever is not a recovery strategy, and restarting a failed process should not reset an account-wide limit. The urllib3 Retry documentation explains configurable backoff, retryable statuses, and header handling.
Add jitter when several workers retry together
If ten workers receive a 429 at the same moment and all sleep for exactly eight seconds, they may all hit the server again together. Jitter introduces a small random difference between retry delays, spreading requests across time. It is particularly useful when multiple queues, containers, or scheduled jobs share one API key.
Jitter does not replace a shared rate limiter. Workers still need to coordinate a common request budget. Randomizing an excessive request rate merely makes overload less synchronized; it does not make the overall load acceptable.
Configure a bounded retry policy in Python
For a requests-based scraper, a Session with an HTTPAdapter and urllib3 Retry can manage ordinary transient failures. A focused policy should retry safe read operations, recognize 429 and selected server errors, respect Retry-After, and stop after a small number of attempts. Set a request timeout separately so a stalled connection cannot occupy the job indefinitely.
The following example illustrates the configuration for an authorized read-only endpoint. It is a starting point rather than a complete scheduler, and a long Retry-After may still require pausing the whole job instead of sleeping inside a request:
import requests
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry

policy = Retry(
    total=3,
    backoff_factor=1,
    status_forcelist=[429, 500, 502, 503, 504],
    allowed_methods={"GET", "HEAD"},
    respect_retry_after_header=True,
)
session = requests.Session()
session.mount("https://", HTTPAdapter(max_retries=policy))
response = session.get("https://example.com/api/items", timeout=20)
response.raise_for_status()
Avoid retrying requests that change data
Do not automatically repeat form submissions, purchases, uploads, or other state-changing requests just because a response was slow. A request may have succeeded on the server even when the client missed the response. Repeating it can create duplicate records or transactions. Restrict the basic retry policy to GET and HEAD unless the destination documents an idempotent workflow.
Similarly, do not respond to 403 or login failures by cycling identities or bypassing access controls. Check credentials, permissions, terms, and the official API. A legitimate scraper should respect a refusal rather than trying to conceal its origin.
Control concurrency across the entire pipeline
A delay inside each worker does not control the combined rate when many workers operate simultaneously. Five processes each sending one request per second still produce five requests per second. Use a shared queue, token bucket, or central scheduler when workers share the same site, account, or API credential.
Separate global concurrency from per-host concurrency. A crawler collecting from several authorized sources may safely use different budgets for each, while keeping a lower limit for a particularly sensitive endpoint. Adjust limits downward when 429 responses increase rather than adding more workers to clear a backlog.
Reduce requests through caching and conditional fetches
The most reliable way to avoid rate limits is to avoid fetching data that has not changed. Cache stable resources and use conditional HTTP requests with ETag or Last-Modified when the server supports them. A 304 Not Modified response can eliminate unnecessary response-body transfers, although the request itself may still count toward a quota.
For recurring collection, incremental scraping can prioritize newly created or modified records instead of downloading an entire catalog every night. Keep refresh intervals proportional to how often the information actually changes.
Make pagination resumable without duplicate records
Rate limits are especially disruptive halfway through a long paginated crawl. Save the last successfully completed cursor or page and commit extracted records in small, validated batches. If the job pauses, it should continue from the checkpoint instead of restarting at page one and repeating hundreds of requests.
Use stable record identifiers to make writes idempotent. If a page is fetched twice after a timeout, an upsert or duplicate check should prevent the same product from appearing twice. The web scraping data quality pipeline approach also helps separate transport errors from actual changes in source content.
Monitor more than the number of 429 responses
Record requests per minute, successful pages, retry counts, response times, timeouts, and the percentage of requests returning each status. Track which host and endpoint caused the problem without exposing credentials in logs. A rising 429 rate often reveals a workload change, an additional worker, or a reduced service quota.
Set alerts for sustained throttling and falling data coverage. If the scraper completes with only half its expected records, treating the run as successful hides a serious quality problem. A reliable process distinguishes completed, paused, partially completed, and failed runs.
Investigate whether the site or workflow changed
Rate limits can appear after a site changes its APIs, pagination, authentication, or caching behavior. A formerly efficient extraction path might start making repeated requests because a selector fails or a cursor no longer advances. Inspect the request log for repeated URLs and unexpectedly high fetch counts.
Use website change monitoring to detect those regressions early. Fixing an accidental loop can eliminate throttling without changing the server-facing rate at all.
Know when to stop and use another permitted source
If a site consistently returns 429 despite conservative pacing, pause the collection and review its documented limits. An official API, bulk download, partner feed, or licensed dataset may be more reliable than repeated page requests. Some websites simply do not permit the collection method a project originally planned.
For web scraping workflows, success should mean accurate, permitted, repeatable collection rather than extracting every page at any cost. Respecting the source makes the process more sustainable for both parties.
Conclusion
Handling HTTP 429 errors well starts before the first failure. Budget requests, coordinate concurrent workers, avoid redundant fetches, and make progress resumable. When throttling occurs, inspect the status and Retry-After guidance, apply bounded backoff with jitter where appropriate, and stop instead of endlessly retrying.
These safeguards turn a fragile script into a maintainable data pipeline. They also make failures easier to diagnose: a paused job with a clear checkpoint and useful logs is far better than a scraper that keeps hammering a server while silently returning an incomplete dataset.